I do not expect many people to use a dedicated MCP server for this blog. But it was a fun project, and it makes a small example you can follow if you want to expose your own content through MCP.
The server lets an AI assistant search the posts and read an article inside a conversation. Asking it to find posts about parallel agents is one way to try it out.
The website still runs as a static Next.js export. The MCP server runs on the user's computer and fetches the published articles over HTTPS, so there is no extra backend behind the blog. This post walks through the pieces, from generating the article feed to connecting the server to Claude Code.
A local server with a remote source
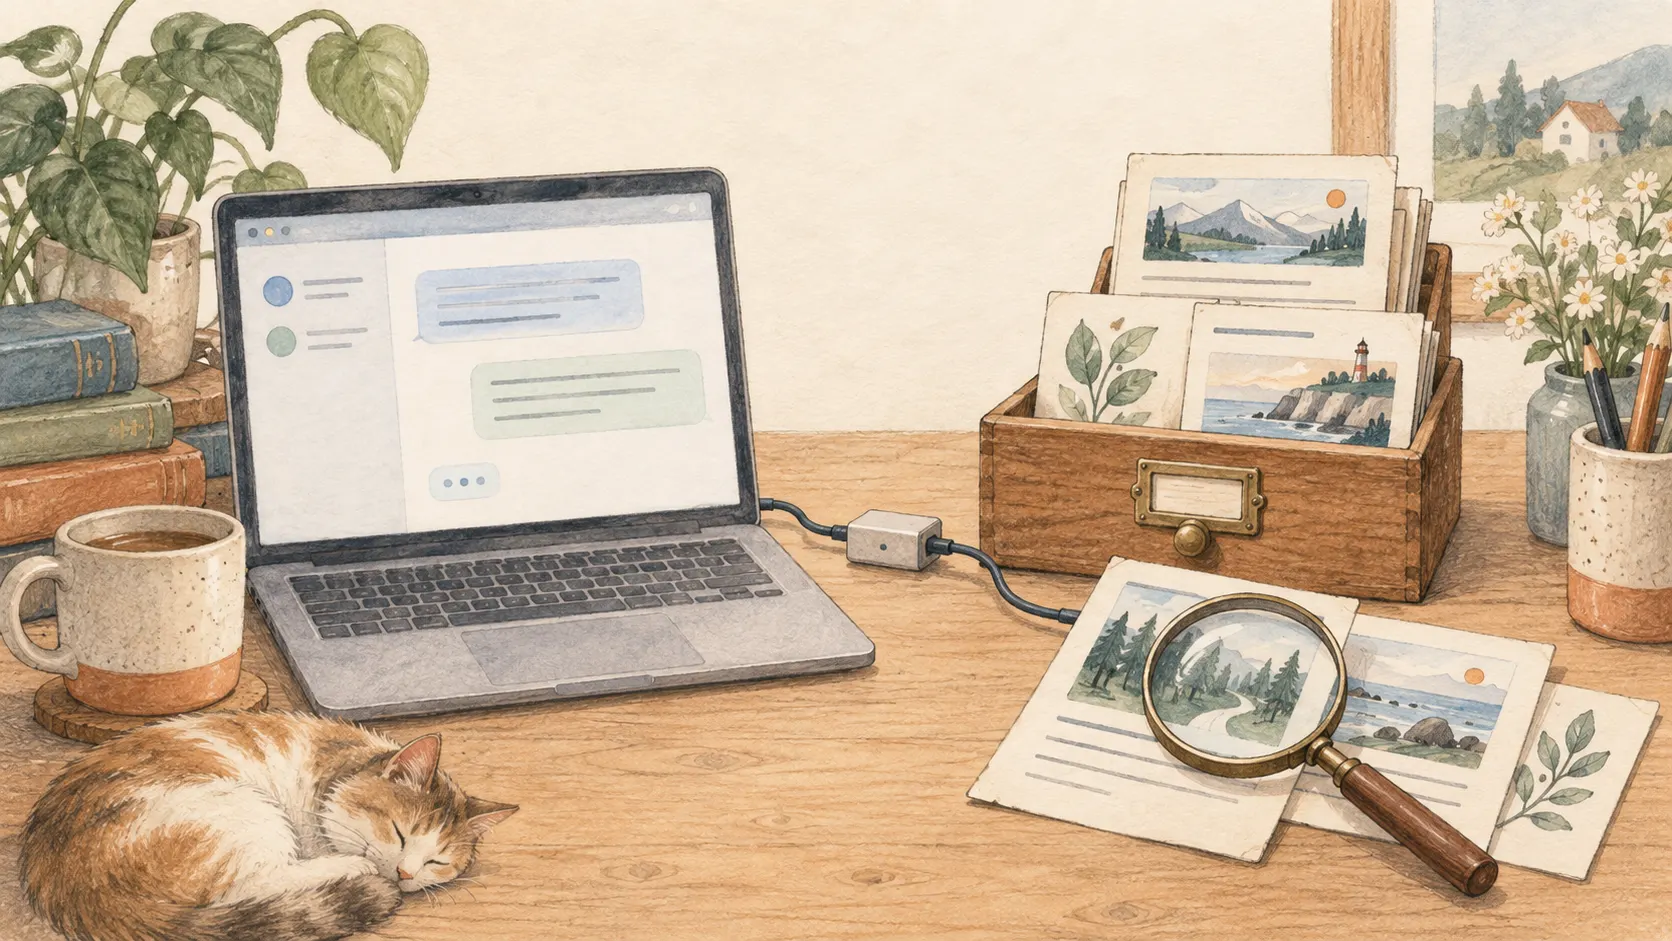
Claude Code starts the MCP server as a program on your computer. They exchange tool calls and results over stdio, short for standard input and standard output. The server fetches articles from the website over HTTPS.
Claude Code
    ↕ MCP messages over stdio
Local blog MCP server
    ↓ HTTPS request
Static blog: /articles.json
The website only serves a JSON file. The local program handles MCP using the TypeScript SDK.
Give the articles a stable format
The blog already reads Markdown files to build its pages. I reused that code to generate an article feed containing the published posts.
Here is an example entry:
{
  "schemaVersion": 1,
  "articles": [{
    "slug": "example",
    "title": "An example article",
    "date": "2026-09-16",
    "tags": ["AI"],
    "url": "https://www.rasmusolsson.dev/posts/example/",
    "excerpt": "A short introduction.",
    "content": "The full article in Markdown."
  }]
}
The feed contains the same posts as the website. The server checks schemaVersion before reading it. New posts appear after a normal blog deployment, without an npm package update.
Expose tools
The server offers three operations:
| Tool | What it returns |
|---|---|
list_articles | Titles, excerpts and links, optionally filtered by tag |
search_articles | Matching articles ranked by keyword relevance |
get_article | The full Markdown content and link for a selected slug |
The assistant searches first, then reads the posts it needs. List and search return short summaries in small batches.
Each tool has a description, rules for its inputs and a function that handles the request. These tell the assistant what the tool does and how to call it.
Here is a shortened version of the reading tool. It assumes server, store and Zod (z) are already set up:
server.registerTool(
  "get_article",
  {
    description: "Read a blog article using a slug returned by search.",
    inputSchema: { slug: z.string().trim().min(1) },
  },
  async ({ slug }) => {
    const article = (await store.load()).find(a => a.slug === slug);

    return {
      isError: !article,
      content: [{
        type: "text",
        text: article
          ? JSON.stringify(article)
          : "Article not found. Search for a valid slug first.",
      }],
    };
  }
);
The full implementation also handles download errors. All three tools are read-only.
The server checks the downloaded data and caches it for five minutes. Search matches keywords in titles, tags and article text. Title and tag matches rank higher.
Connect it to Claude Code
The server is distributed as the npm package @raholsn/blog-mcp. With Node.js 22.14 or newer and Claude Code installed, run:
claude mcp add --transport stdio --scope user rasmus-blog \
  -- npx -y @raholsn/blog-mcp@latest
Claude Code launches the server for you. --scope user makes it available across projects. Use /mcp inside Claude Code to check the connection. Configuration reference.
Then ask:
Find Rasmus's articles about parallel agents, then read the most relevant post.
Claude can use the tools directly, without a separate skill. Other MCP clients that support stdio can also run the server.
Wrapping up
This was a fun little addition to the blog. If you have been thinking about building an MCP server for your own content, I hope this gives you a few ideas to try. You can find the full example in raholsn/blog-mcp.
Happy coding!